
Led the end-to-end design of a new workflow for evaluating conversational voice agents- from product definition and stakeholder alignment to interaction design and deployment readiness.
Role
Lead UX Designer
Timeline
4 months
Outcome
Successfully shipped V2 (MVP++)
Team
Research, PM, Engineering, Content and Leadership
Introduction
ServiceNow already has a way to test AI agents that respond in text - automatically running them through hundreds of scripted conversations and scoring the results. This project built the equivalent for voice agents and assistants, the ones you talk to on a phone call.
Why existing evaluation platform couldn't be reused

A phone call isn't just a text chat with sound added on top
It wasn't simply enough to copy the existing paradigm directly, there were several technical and product limitations.
Chat agent/workflow | Voice agent/assistants | |
|---|---|---|
Format | Text input and output | Speech input, spoken both sides |
Speed | Runs in seconds | Runs closer to real length of call |
What can go wrong | Wrong words. wrong facts | Also; bad timing, talking over the caller, mishearing due to noise |
What counts as "correct" | The right answer, written clearly | The right answer, said in the right tone, at the right moment |
How mature the tool is | Proven, widely used | Being built for the first time |
Voice modality carries a lot more complications and simply copying the existing paradigm wouldn't work.
The hardest early questions
It wasn't "What should this look like?" it was
"what are we even evaluating?"
Workshops with product and engineering surfaced real disagreements: how much should voice agent evaluations borrow from chat agent evaluation vs how much should be designed fresh? what counts as a "correct" response when tone and timing matter as much as content?
How were other teams approaching voice evaluations?
We also took a look at what the other early players in the market were doing and how they were doing it. The major themes that came out from those were.
These were the major themes that came out
Voice bhaviour and latency
Most players evaluated not just what was said, but timing, response delay, accuracy, interruption handling and pacing
Testing and QA
How test conversations were generated and scored, and how much was manually evaluated or scored.
Analytics
How raw scores were turned into something a team could actually work on, rather than a list of pass/fail.
Platform integration
How tightly the eval tool needed to plug into existing agent-building and deployment pipelines to get adopted.
Where does Voice Agent Evaluations fit into the overall agentic ecosystem?
It primarily fits into the build-test-evaluate cycle before the agent is actually deployed to actual users. Agents need to be stress-tested and made sure that they are foolproof before it goes into production. Evaluations help there by testing the agent on a large varied dataset.
The most complicated part of the process
It was setting up and selection of the datasets. Since the quality of the data decides the quality of evaluation and the subsequent suggested fixes, a lot of emphasis and time was spent on the datasets. To make it easy to set up while also including all the inputs that are required for its quality.
What everyone agreed on
All stakeholders agreed on simplifying the information architecture of the datasets.
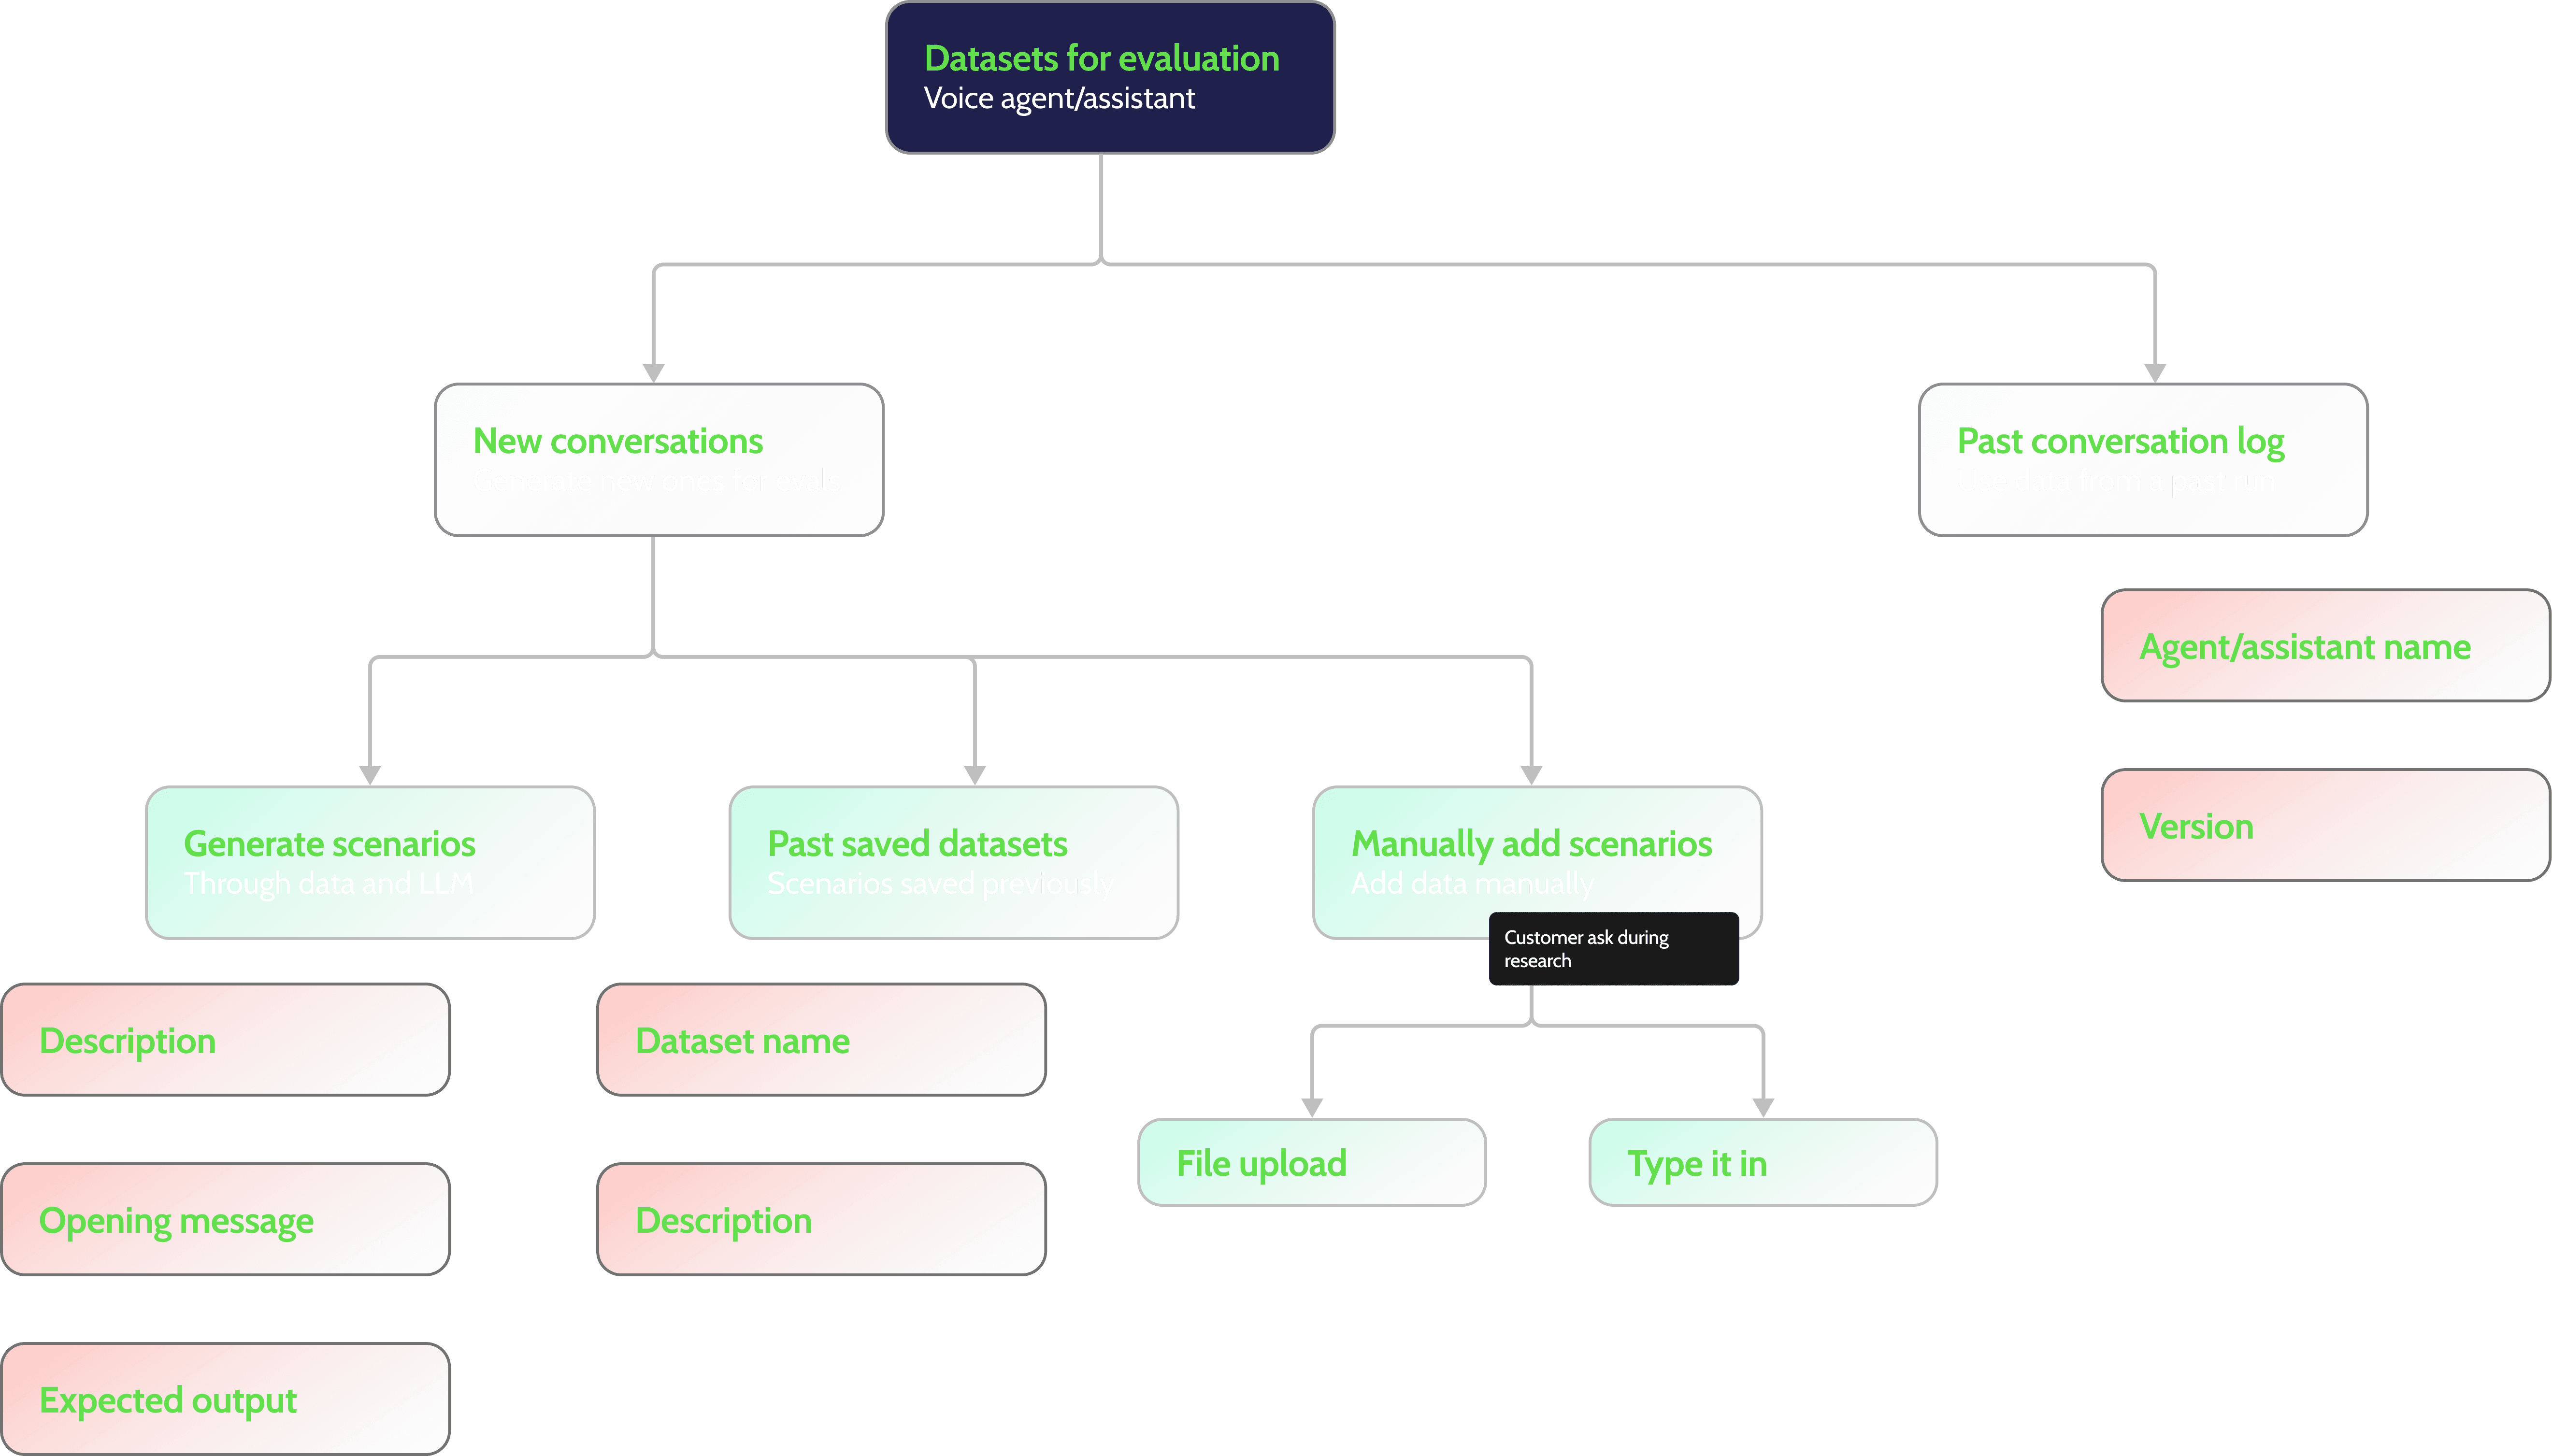
Basically all datasets should have the following information-
What everyone didn't agree on
This was on the logic to generate the datasets from these inputs. Two types of combining these inputs
Scenarios x Persona x Environment (All permutations and combinations) | Scenario + Persona + Environment (Randomizing the combination) |
|---|---|
Pros: | Pros: |
Cons: | Cons: |
The other factor was engineering bandwidth and how we should approach building these features according to their order of importance. We ultimately decided to build it in this order.
Scenarios → Background noise toggle → Background noise selection → Persona selection
Hence for this approach, Scenario + Persona + Environment would be a good approach to build it with since it combines engineering flexibility while maintaining a steady feature addition which would feel natural and not confuse the user with mathematical logic.
Here are wired flow I put together to make that call on how it should be.


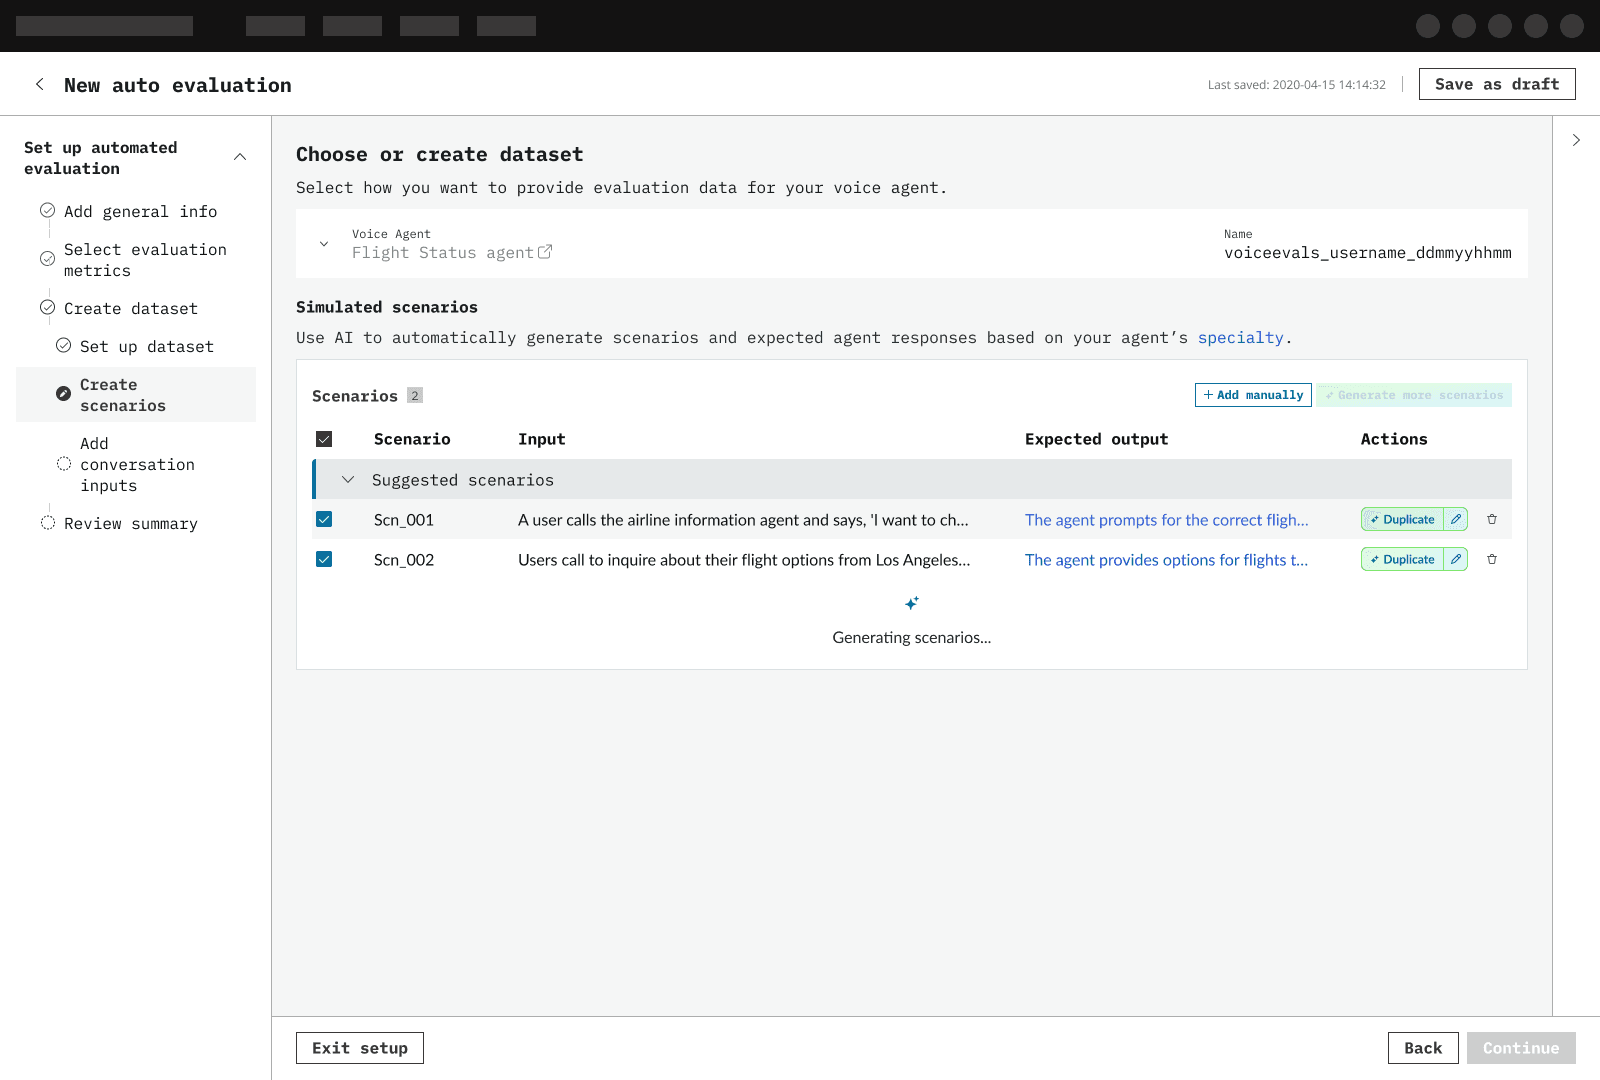
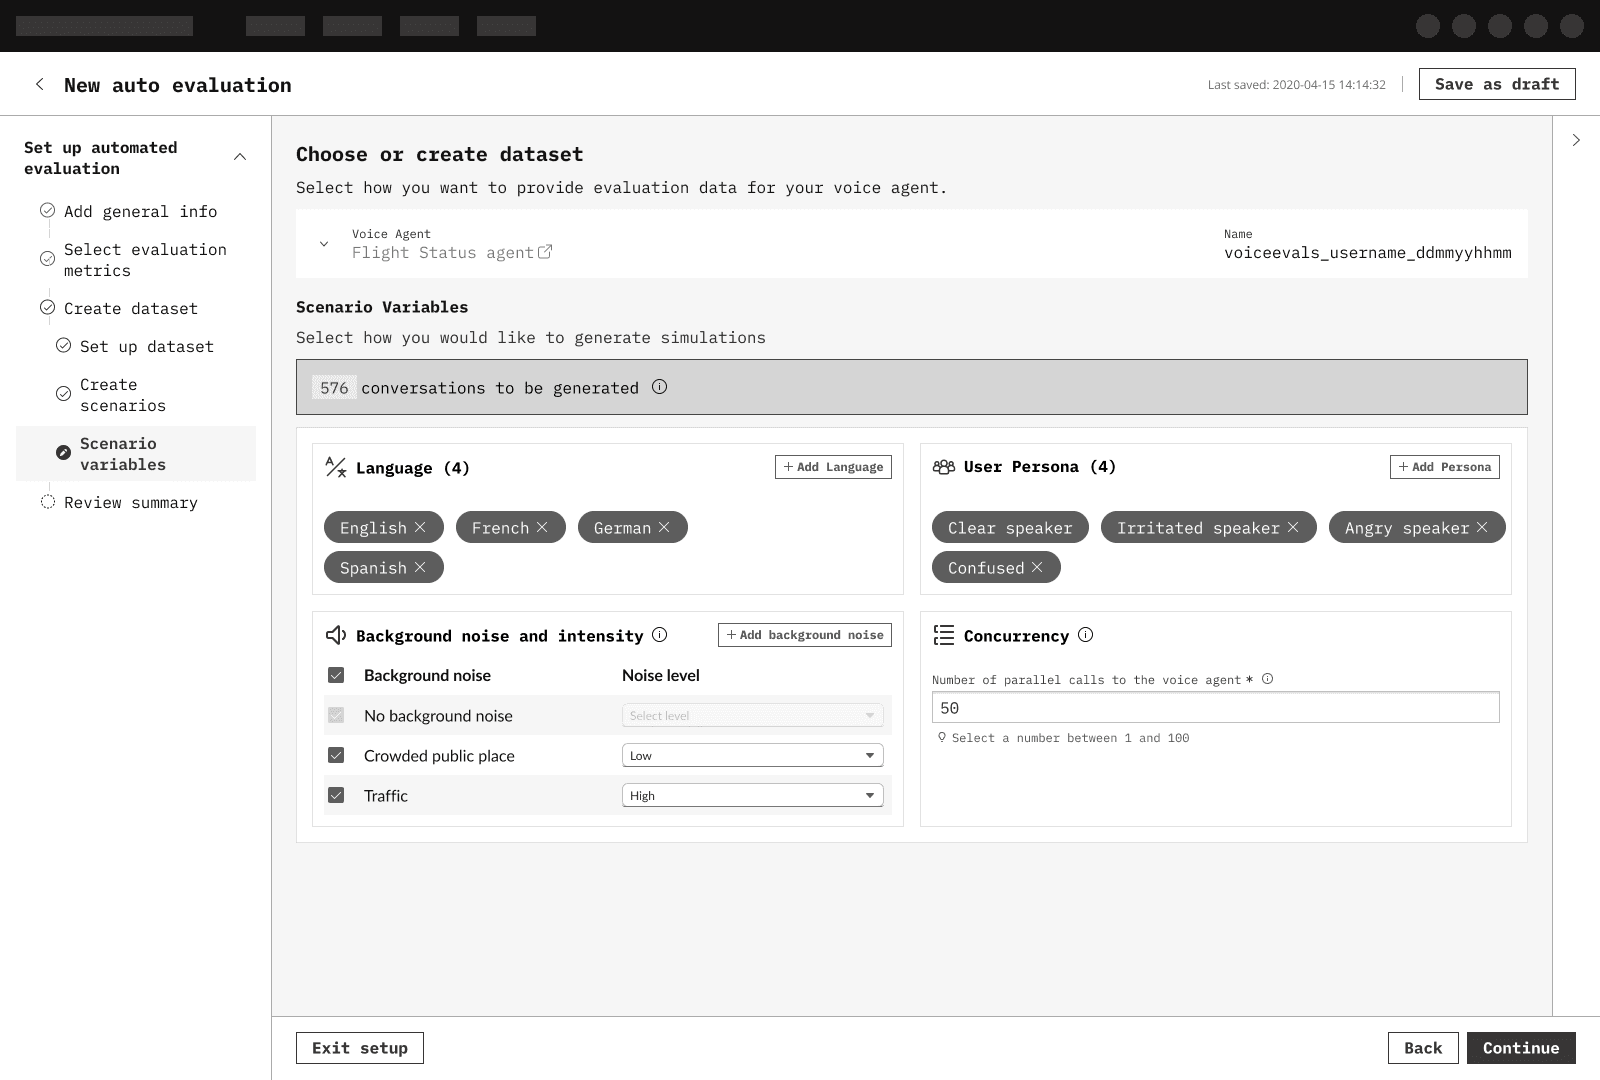
This was the basic flow for scenario generation which was shared with stakeholders for their feedback. Based on feasibility and usability, other iterations were created on top of this and again feedback gotten to finalize on a flow.
What was the final flow for the evaluations?
Evaluation is a cyclic process and continuous improvement is measured at each run. What we saw earlier was just the 3rd step of the process (dataset).
Other "surprises" that nudged the design
Scenario generation takes a bunch of time (few minutes for 10s of scenarios).
The evaluation as a whole takes few hours to run and complete.
Sub-steps are not possible to build and everything needs to be on one single screen.
Want to know how I built it from here on?
What was the impact of the product?
Established the organization's first AI Voice Agent Evaluation workflow
Before this, there was no repeatable way of testing Voice AI agents before they were shipped.
Built an extensible framework for test data addition
So that new test data can be added through multiple methods rather than one fixed pipeline - designed to keep pace as agent use diversified.
Created a scalable model for expansion to other modalities
This evaluation approach can scale beyond voice as new agent types come online - reducing the need to redesign the paradigm from scratch.
